NVIDIA H100 vs H200
Compare NVIDIA H100 and H200 side by side: compute, memory, and pricing. H100 runs on-demand on VESSL Cloud from $2.98/hr. H200 (141GB HBM3e) is reserved VM Cluster capacity.
from $2.98/hr
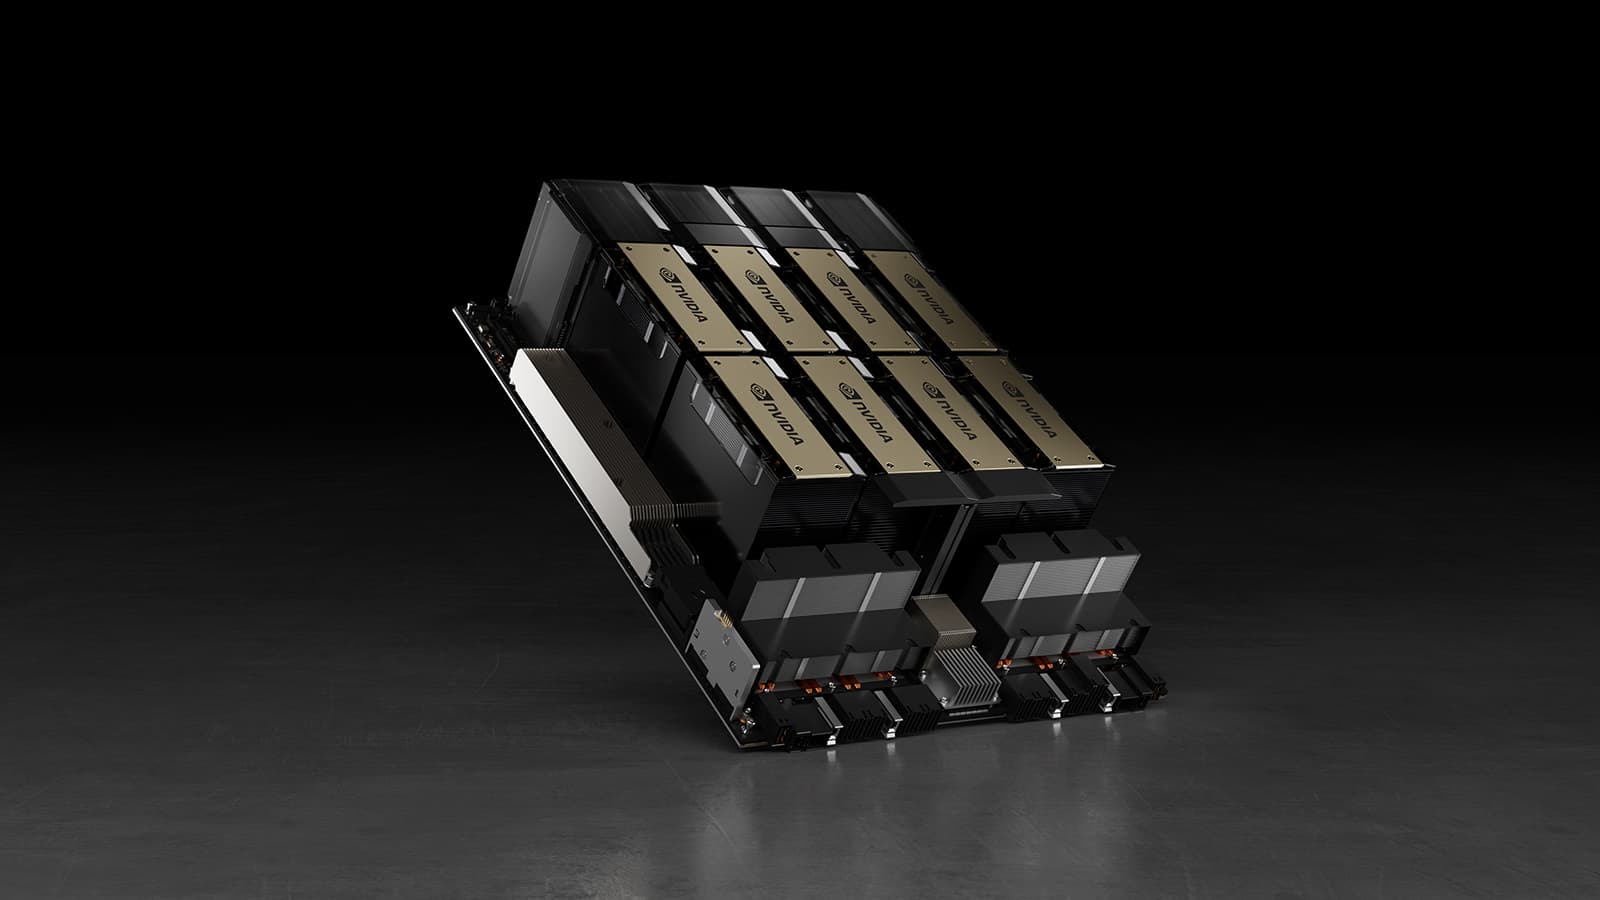
- GPU memory
- 80GB HBM3
- Memory bandwidth
- 3.35 TB/s
- GPU memory
- 141GB HBM3e
- Memory bandwidth
- 4.8 TB/s
Technical specifications
H100 NVIDIA H100 SXM | H200 NVIDIA H200 SXM | |
|---|---|---|
| Architecture | Hopper | Hopper |
| GPU memory | 80GB HBM3 | 141GB HBM3e |
| Memory bandwidth | 3.35 TB/s | 4.8 TB/s |
| NVLink | 900 GB/s | 900 GB/s |
| FP16/BF16 (Tensor) | 1,979 TFLOPS | 1,979 TFLOPS |
| FP8 (Tensor) | 3,958 TFLOPS | 3,958 TFLOPS |
| Max TDP | 700W | 700W |
| GPUs per node | 8 (HGX H100) | 8 (HGX H200) |
*Peak performance with sparsity, per NVIDIA official specs. Final specs may vary by node configuration.
Pricing & availability
What's Hopper best for?
Large-scale LLM training & fine-tuning
Run 70B–400B-class training on a proven Hopper stack: FP8 tensor cores, multi-node InfiniBand on VM Clusters, and NeMo and Megatron support.
High-throughput LLM inference
H200's 141GB HBM3e fits 70B-class models in FP8 on a single GPU, while H100 FP8 keeps token throughput high and tail latency low.
Research & HPC
Mature CUDA, PyTorch, JAX, and NeMo ecosystem: spin up H100 GPUs on demand for experiments and scientific compute.
Why AI teams run GPUs on VESSL Cloud
From A100 to Blackwell Ultra
Run A100 and H100 on demand. Reserve H200 and Blackwell GPUs for larger runs, so each workload gets the GPU it needs.
Issues caught early
Every VM Cluster node is health-checked continuously, with its status refreshed about once a minute. Workspaces and Jobs alert you when a run crosses a resource threshold or hits a runtime issue.
From one node to a cluster
Train and serve on up to 8 GPUs on one node, and move to a multi-node VM Cluster when one node is not enough.
Enterprise-ready
SOC 2 Type II compliance, with dedicated support for production AI.
Frequently asked questions
How much does an NVIDIA H100 cost on VESSL Cloud?
H100 SXM (80GB) starts at $2.98/hr on-demand. Provision it self-serve at cloud.vessl.ai.
What's the difference between the H100 and H200?
Both share the same Hopper compute, but the H200 carries 141GB of faster HBM3e memory (vs 80GB HBM3 on the H100) at 4.8 TB/s bandwidth, fitting larger models, bigger batches, and longer context windows.
How do I get access to NVIDIA H200 GPUs?
H200 runs as reserved VM Cluster capacity. Talk to our team for current availability and pricing.
Can I run multi-node H100/H200 training?
Yes, on a VM Cluster: HGX H100 or H200 nodes (8 GPUs each) joined by high-speed InfiniBand for distributed training.
Where AI models
get their GPUs
- Self-serve on-demand GPUs
- Scale to multi-node clusters
- Reserved terms on H200 and Blackwell
- Dedicated support